151M conversations stolen to distill Claude Opus
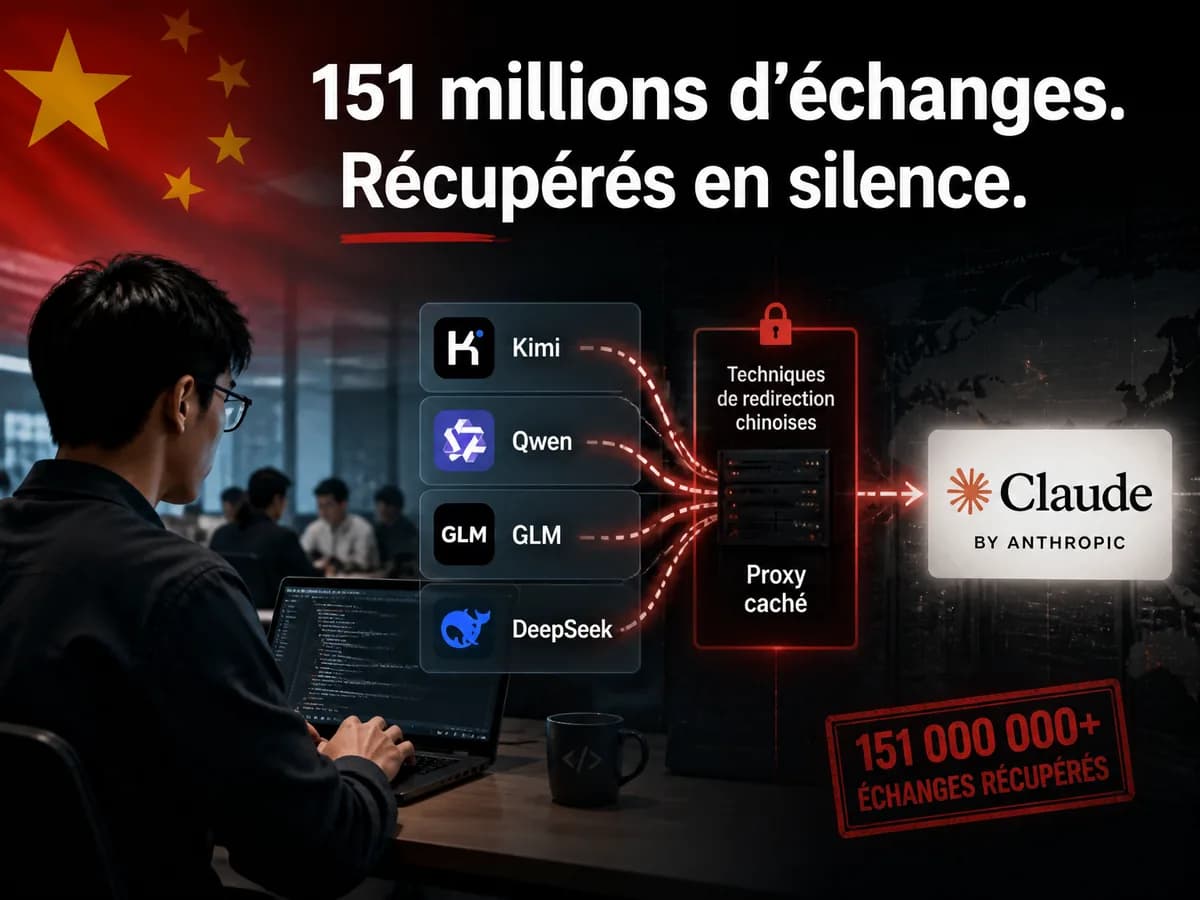
According to Anthropic, requests to the Chinese models Kimi and DeepSeek were rerouted to Claude Opus for distillation purposes.
A 154-page report, 7 categories of abuse
Yesterday, Anthropic published its new threat intelligence report: across 154 pages, it details the 7 categories of abuse the company faced. Unsurprisingly, distillation is on the list. Distillation means using an advanced model (like Claude) to generate answers, then using them as training data for a cheaper-to-run competing model.
Alibaba, Moonshot, DeepSeek: the numbers
According to Anthropic, 5 Chinese labs ran massive campaigns to extract Claude Opus's reasoning:
- Alibaba (Qwen): the largest ever measured. 151M exchanges over 3 months, peaking at 3M per day, 3,500+ fraudulent accounts. The reasoning transcripts were used to train Qwen 3.5, 3.6 and 3.7.
- Moonshot (Kimi): the most unsettling. For 10 days, they relayed nearly 300,000 customer requests to Claude instead of Kimi. Users believed they were talking to a Chinese model. Opus was answering.
- DeepSeek: same scheme, targeting devs going through Claude Code or OpenCode. 12.1M exchanges in 14 days.
- Zhipu (Z.ai) and Xiaomi: same war, different scales.
Account farms and cross-session replay
Technically, the labs relied on account farms (residential proxies, disposable emails, virtual cards), an injected prompt forcing the model to write its reasoning in clear text, then a cross-session replay attack to bypass the thinking signatures.
Customer data inside the relayed exchanges
The relayed exchanges contained customer data. Production credentials, the specs of a tech company's AI program, CCTV feeds, personal data of hundreds of US and European users going through third-party model routers. Anthropic writes that these practices are "probably incompatible with privacy laws".
That said, some perspective is in order. First, these are Anthropic's allegations, attributed "with high confidence" — not a court verdict. Second, the report notes that Fable, their best-protected model, held the line: Zhipu eventually targeted Opus "because the safeguards were weaker".
Model reasoning has become an industrial target. Our prompts have become collateral damage.
I keep wondering about LLM gateways and other third-party aggregators.
Sources
- www-cdn.anthropic.com/e50be2e51e7695dc4b1366a37a245a597377d3b5/Anthropic-Detecting-and-countering-091026.pdf
- x.com/IntCyberDigest/status/2098149671957103005
- www.anthropic.com/threat-intelligence-report-september-2026
- www.bloomberg.com/news/articles/2026-09-10/moonshot-secretly-routed-user-requests-through-claude-anthropic-says